
For many, a website is either available or unavailable. A page loads, an application responds, or an error message appears. Behind this pleasant experience lies a wealth of technology that prevents interruptions before the user even notices them. Because every component has its limitations, large digital platforms rarely rely on a single server or internet connection. Hardware maintenance, software updates, changes in network paths, and unexpected traffic spikes are all possible. Maintaining service availability requires a design that prevents a single failure from causing a service outage.
This strategy is becoming increasingly important as companies use digital platforms 24/7. Online banking, cloud collaboration tools, streaming services, healthcare systems, e-commerce platforms, logistics networks, and communication applications must be accessible regardless of local time zones or regional opening hours. This reliability does not depend on powerful hardware, but rather on building a solid architecture that distributes responsibilities across numerous independent components.
Eliminating Single Points of Failure to Improve Availability
Preventing service interruptions caused by component failures is a fundamental principle of high-availability systems. A single point of failure occurs when every user request depends on a single database server, internet connection, or storage device. No matter how reliable, all equipment and software require maintenance or are susceptible to unexpected problems.
Modern platform architecture addresses this issue through redundancy. Multiple servers can perform the same tasks, storage devices can store critical data, and the network infrastructure typically has multiple communication paths. If one component fails, another is ready to take over support. Although this approach also handles failures, it limits their impact. Another system can take over the service before users realize that a server has failed.
Sharing Workloads Instead of Centralized Processing
As the number of users on digital platforms grows, it becomes impractical to handle all requests with a single machine. Even with continuous server operation, the processor, memory, storage, and network bandwidth reach their limits. Modern platforms distribute the workload across multiple systems instead of centralizing it on a single system.
Whether it is a customer managing a webshop, a user watching streaming video, or thousands of users consulting documents, they may all be using the same platform. Traffic is distributed across multiple application servers capable of performing the same tasks. This load balancing mechanism ensures that machines can handle smaller tasks, thereby improving responsiveness and reliability. The distributed approach simplifies maintenance. Servers can be updated or replaced while other servers continue to provide service to users, allowing the infrastructure to evolve without service interruptions.
Common Components for High-availability Infrastructure
Large digital platforms typically use complementary components.
- Multiple application servers process queries.
- Critical data is protected by redundant storage.
- Database independence.
- Efficient traffic load balancers.
- Backup networks.
- Infrastructure status monitoring systems.
- Automated error recovery.
Instead of addressing each reliability issue individually, we let the components work together to improve platform availability.
Monitoring is Platform-based, Not Reactive
Continuous availability involves more than just troubleshooting. Modern infrastructure monitors processors, memory, storage, response time, network connectivity, and application activity. These measurements enable operational staff to detect problems before they affect users.
If there is insufficient memory, application servers may become less responsive. Monitoring systems can detect this trend before users notice the slowdown. Administrators can investigate the problem, or automated systems can redirect maintenance requests to servers that are functioning better. This proactive approach makes monitoring an operational tool, not a diagnostic tool. It actively drives decisions that prevent future failures, rather than focusing solely on past failures.
Automation is Essential for Continuous Operation
On large digital platforms, human intervention cannot guarantee service availability. Hardware failures, traffic spikes, software installations, and infrastructure maintenance can all occur when administrators are busy or team members are geographically dispersed. Automation fills this gap by performing specific actions under specific circumstances. During periods of high demand, more application servers can be started, unhealthy systems can be automatically taken out of service, backups can be initiated according to scheduled processes, and routine maintenance can be performed without human approval.
Automation enables technical teams to plan and resolve issues, while it performs repetitive operational tasks independently in the background. As digital platforms continue to evolve, the collaboration between automated systems and human management has become a hallmark of high-availability infrastructure.
Scalability versus Availability
Scalability and availability are sometimes used interchangeably, but they address different issues. A platform can serve millions of users, but if a critical component fails, the platform goes down. A high-availability service can remain online but cannot handle sudden traffic spikes. Large digital platforms plan for these two scenarios separately. Availability refers to maintaining service operation in the event of an outage, while scalability refers to accommodating growth without compromising performance. These two goals complement each other, but they do not necessarily connect.
Take online education at the start of a new school year, for example. Traffic can increase rapidly. Adding application servers can help spread demand, but if all servers depend on the same database, the service can still be interrupted if that database fails. A reliable platform can strike a balance between growth and resilience.
Geographic Location Improves Resilience
When digital services are distributed globally, relying on local infrastructure becomes problematic. No matter how well servers are maintained, natural disasters, regional network outages, maintenance, or power failures can affect operation across the entire region.
Many large platforms implement infrastructure in multiple regions to reduce reliance on local availability. If a data center fails, services can distribute the workload across other data centers, ensuring operational continuity. Geographic distribution improves resilience and offers another advantage. Users typically experience faster responses when requests are processed closer together. European customers may experience faster response times from local infrastructure than from servers on other continents. Modern platform designs take geographic location factors into account when planning performance and availability.
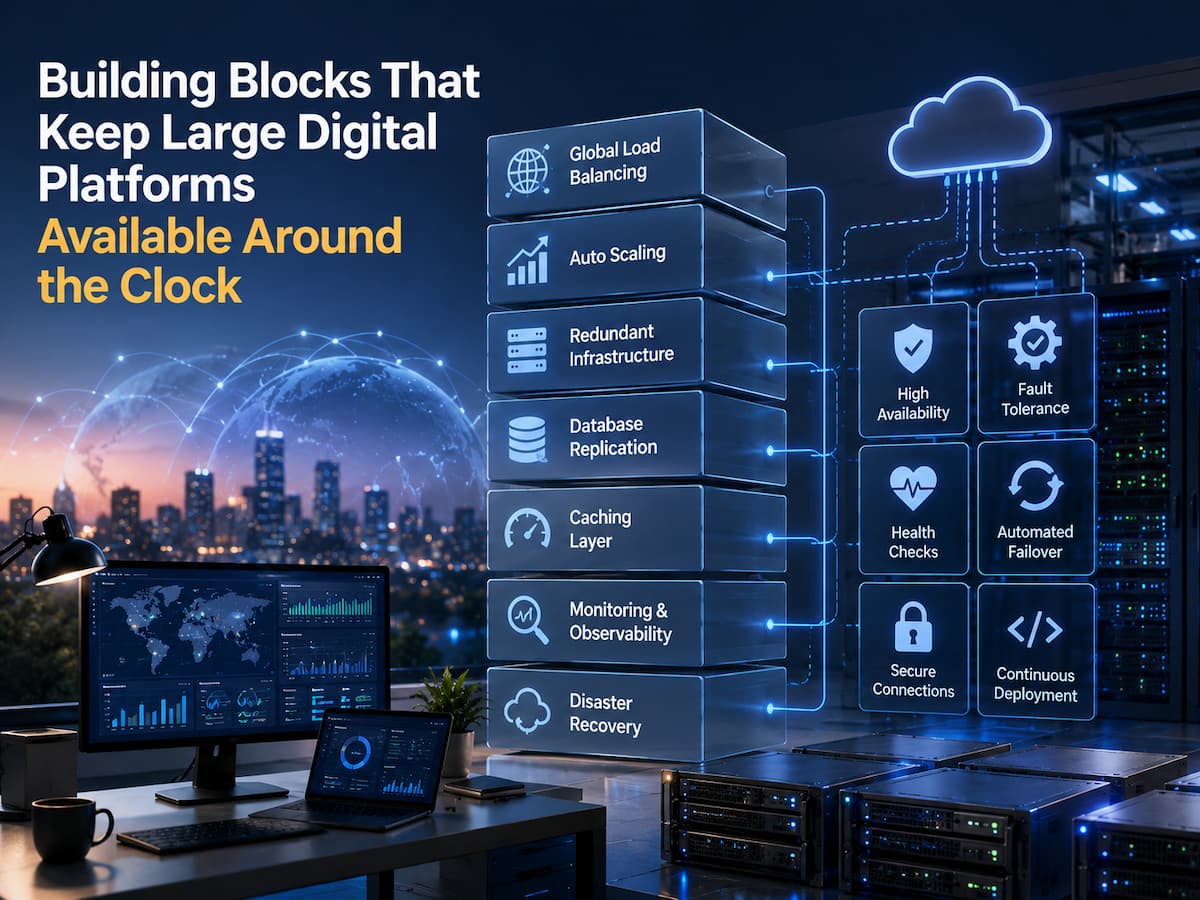
Building Blocks That Support Continuous Availability
Although implementations vary, many large-scale platforms rely on a combination of technologies working together.
| Infrastructure Component | Primary Purpose |
|---|---|
| Load balancers | Distribute incoming requests across available servers. |
| Redundant servers | Continue processing if individual machines become unavailable. |
| Replicated databases | Preserve access to important information during failures. |
| Monitoring platforms | Detect performance issues and infrastructure health changes. |
| Automated recovery systems | Respond quickly to predefined failure conditions. |
| Backup infrastructure | Protect services during maintenance or unexpected outages. |
No single component guarantees uninterrupted operation. Continuous availability results from these elements supporting one another throughout the platform.
Maintenance Should Not Require Complete Downtime
All digital platforms require software updates, hardware repairs, configuration changes, and security upgrades. If the service has to be shut down for every maintenance, companies will struggle to provide a reliable online experience. Modern infrastructures address this problem with incremental maintenance. Instead of updating all servers at once, administrators remove a small part of the infrastructure, perform the maintenance, test it, and then restore it to operation. This process is repeated for the remaining components.
Most users can continue to use the operational infrastructure during maintenance, meaning this incremental approach minimizes disruption. Even if we implement significant improvements in the background, the platform remains available to users. Planning is crucial for infrastructure because organizations cannot eliminate failures entirely; they must prioritize recovery just as much as prevention.
Reliability Depends on Preparation
Highly available platforms typically prepare for situations that may never occur.
- Hardware failures.
- Unexpected traffic spikes.
- Network interruptions.
- Software defects.
- Storage problems.
- Power-related incidents.
- Planned maintenance activities.
Preparing for these possibilities does not mean they are expected every day. Instead, resilience comes from ensuring the platform already has procedures and infrastructure capable of responding when unusual conditions arise.
Availability Also Depends on Recovery
Even the most advanced platforms cannot completely prevent all possible failures. Hardware can fail unexpectedly, software updates can cause problems, and external network providers can experience outages over which the organization has no control. Because we cannot completely rule out failures, recovery is just as important as prevention.
Most digital systems today include robust recovery processes that restore normal operation as quickly as possible. Some steps are automated, while others require analysis by the technical team and a well-considered judgment based on the nature of the problem. Recovery planning therefore goes beyond the technology itself and encompasses operational processes, testing, documentation, and communication between various teams. Organizations typically practice these processes before an actual crisis occurs. Simulating failures verifies whether your backup infrastructure, monitoring, and recovery processes are functioning properly. This way, you have less to worry about when a real crisis occurs.
Continuous Availability Is the Result of Many Coordinated Decisions
Today’s largest digital platforms are reliable because of their robust architecture, not because of a single technology. Redundant infrastructure, distributed workloads, automated recovery, continuous monitoring, geographic distribution, and well-planned maintenance all point to the same goal: ensuring that the service remains available under all circumstances.
Most people don’t even notice these systems because they are designed to run silently in the background. However, all successful logins, purchases, streaming video, or collaborative documents depend on an infrastructure capable of recovering from failures without causing widespread service interruptions. As digital platforms continue to expand to serve more users, devices, and connected services, these building blocks will continue to play a crucial role in providing an ever-growing, reliable online experience.
FAQs
1. Is high availability the same as a powerful server?
No. Better hardware certainly helps, but high availability means that the service remains available even if one or more components fail or are out of service for maintenance.
2. Why are large platforms built on multiple servers instead of one large machine?
Multiple servers mean less dependency on a single system, a more efficient distribution of the workload, simpler maintenance, and no impact on the entire service.
3. Redundancy does not mean that all data is replicated.
Not always! Some components are fully replicated, while others are used as backup systems or recovery methods, depending on their location within the platform and the required level of redundancy.
4. Can the platform remain online during maintenance?
Yes. Many modern platforms are maintained by updating only parts of the infrastructure, while the rest of the system continues to provide services to users.