
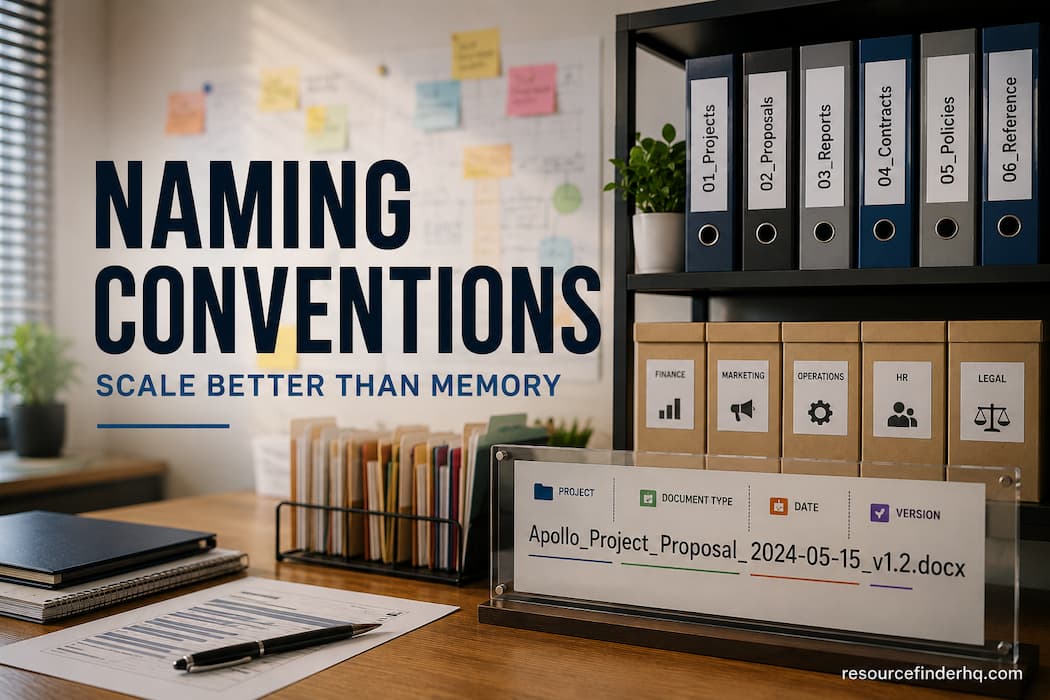
If five people save the same project document, it likely results in five entirely different file names. Some use the project name, others the client name, still others the date, and some simply type ‘Final Version,’ even if multiple updated versions follow. Initially, these differences seem insignificant because everyone remembers what they saved. But months later, with dozens of revisions in shared folders and on cloud platforms, memory alone is not sufficient to determine which file to open.
That is why organizations attach so much value to naming conventions. Naming conventions are not just about making file names neat and aesthetically pleasing or meeting management preferences; their true purpose is to create predictable patterns that remain effective, even long after the file creator has forgotten the details. A well-designed naming convention enables users and software to understand information without having to rely on personal memory or undocumented habits.
Consistency is Often More Important than Creativity
When creating file names, people naturally choose words that are meaningful to them at that moment. Unfortunately, individual logic is not always effectively compatible between different teams or during long-term use. File names that seem self-evident today can become confusing as projects grow, new employees join, or similar documents accumulate. A consistent naming convention reduces this uncertainty because files follow the same structure, regardless of who creates them.
Users do not have to decipher dozens of different naming styles to quickly find information such as project IDs, dates, document types, or version numbers. The file names themselves become a reliable source of information, rather than a puzzle that someone has to solve. This benefit is particularly important in collaborative environments. Team members no longer have to waste time wondering which version is correct, because the naming system provides many answers before anyone even opens the document.
Good Naming Supports More Than Human Readers
Although humans originally devised filenames, modern digital platforms use them in many workflows. Backup software, synchronization tools, document management systems, automated reporting processes, and archiving platforms often use filenames together with metadata to organize information and identify related documents.
Imagine an engineering team that produces hundreds of technical drawings every month. If every drawing follows a predictable naming structure, automated systems can distinguish projects, identify versions, group related files, and generate reports, significantly reducing human intervention. The software does not need to understand the technical content itself, because the naming conventions already contain the majority of the organizational context.
This illustrates an important principle: effective naming conventions improve the efficiency of automation, not because computers need descriptive filenames, but because structured information can be processed by systems more easily and consistently.
Information typically included in filenames
Organizations typically include the following types of information in standardized filenames:
- Project or client identification.
- Document type. Creation or release date.
- Version or revision number.
- Department or business unit.
- Product or asset identification code.
- Geographic region (if applicable).
Not every filename contains all of these elements, but by always using the most relevant ones, the information remains understandable throughout its entire lifecycle.
Naming Becomes More Important as Collections Grow
A personal folder containing twenty documents typically does not require complex naming rules, as manual browsing is still convenient. However, the situation changes drastically when thousands of files need to be shared between departments, synchronized via cloud platforms, or stored for years.
As the file collection grows, minor inconsistencies can gradually escalate into larger problems. Similar documents become difficult to distinguish, duplicate work increases (because existing files are easily overlooked), and teams spend more time checking which version to use. These issues often develop gradually and are easily overlooked until the file repository becomes so large that significant effort is required to correct previous inconsistencies.
Establishing robust naming conventions early on helps prevent these issues. Instead of having to rework thousands of files later, you can create a framework that continuously supports new information as the file repository evolves.
File Names Must Remain Valid
File names often exist longer than the underlying work. Years after a project has been completed, someone may need to retrieve reports for audit purposes, review old designs during product updates, or find documents to support customer requests. By that time, the original stakeholders may have forgotten why they chose certain abbreviations or what an internal nickname means.
Effective naming conventions anticipate this situation by explicitly indicating that they are temporarily useful. File names are not based on personal memory but are carefully designed so that future users can understand them with minimal additional explanation. This long-term perspective simplifies the maintenance of digital archives, because the information remains valid even if the priorities of the team, technology, and organization change.
A well-designed naming system therefore becomes part of an organization’s knowledge infrastructure. It unobtrusively preserves contextual information that memory alone cannot reliably recall—information that accumulates over time.
Naming Conventions Help Reduce Duplicate Information
One of the most common problems in growing digital archives is the gradual accumulation of duplicate files. Sometimes, duplicate files are identical copies stored under different names. In other cases, they involve slightly different versions because someone cannot locate the original document and assumes it needs to be recreated.
Consistent naming conventions can mitigate this risk, as they make existing information easier to identify. When team members look for quarterly reports, they are more likely to find the correct file if the filenames follow a fixed pattern, rather than relying on vague descriptions such as ‘Report_New,’ ‘Latest Version,’ or ‘Final Version.’
Version Numbers Are More Reliable Than Descriptive Words
At the start of creating a document, terms like ‘final,’ ‘updated,’ or ‘latest’ seem useful. However, the problem is that projects rarely stop evolving after just one revision. A file labeled ‘final’ may be followed by versions such as ‘final_new,’ ‘final_v2,’ or ‘truly final,’ leaving no one certain which version is actually reliable.
Structured version numbers solve this problem more effectively because they reflect the evolution of the version, rather than subjective opinions. Version identifiers no longer describe a document with subjective labels but indicate its position within a continuous series of revisions. This consistency is particularly important for collaborative projects. Multiple collaborators can understand the document’s history without relying on email correspondence or personal memories, allowing work to proceed more easily and with greater confidence.
Characteristics of Effective Naming Conventions
Although naming standards vary between organizations, successful systems often share several qualities.
| Characteristic | Why It Matters |
|---|---|
| Consistency | Makes files predictable regardless of who created them. |
| Clarity | Reduces confusion when information is shared widely. |
| Simplicity | Encourages employees to follow the standard consistently. |
| Scalability | Continues working as collections become much larger. |
| Meaningful identifiers | Helps distinguish similar files without opening them. |
| Long-term usability | Keeps filenames understandable years after creation. |
A naming convention does not need to be complicated to be effective. The most successful systems are often those that remain easy to apply every day.
Naming Standards Improve Collaboration Across Teams
Modern organizations rarely keep information within a single department. Project proposals often require approval from the sales, finance, legal, operations, and senior management departments before they become final. If each team uses its own naming style, it becomes increasingly difficult to find the most recent document as the project progresses.
Shared naming standards create a common language between departments. Even employees who were not involved in the original work can easily recognize document types, project identifiers, or revision history based on the file names. This reduces unnecessary communication, as there is no need to ask where information is stored or which document to use. These benefits are even greater when organizations collaborate with external partners, suppliers, or customers. Consistent file names make shared information easier to understand, regardless of who originally created it.
Naming conventions and metadata work together
- File names are just one part of a well-organized information system.
- File names provide immediate context before a file is opened.
- Metadata contains additional descriptive details that file names might not be able to contain. Search indexes use both filenames and metadata to improve retrieval efficiency. Categorization systems organize files based on their purpose.
- Version history preserves information about changes that goes beyond just filenames.
These organizational tools are not substitutes for one another but rather complement each other, resulting in more reliable digital archives.
Predictable Filenames Facilitate Automation
Many business processes depend on software that can automate large volumes of files. Backup systems, document workflows, reporting tools, synchronization platforms, and archiving solutions can often process thousands of records without human intervention. Predictable filenames make these automation tasks easier because the software can consistently recognize patterns.
For example, an organization can configure a workflow for processing monthly financial reports that follows a predefined naming structure. Because each report contains the same sequence of identifiers, the system can identify incoming files, place them in the correct location, and trigger other business processes without human intervention. Automation does not rely entirely on filenames, but consistent naming reduces ambiguity and ensures that software can interact more reliably with large datasets.
Standardized Naming Promotes Standardized Information
Filenames may seem unimportant, but in large digital archives, they are often among the first pieces of information users encounter. Consistent naming conventions reduce confusion, promote collaboration, improve automation, and ensure that documents remain easy to understand long after their creation. Organizations can build predictable structures that continue to function as information grows, without relying on personal memory.
As digital collections expand across cloud platforms, shared workspaces, and long-term archives, well-designed naming conventions remain one of the simplest and most effective ways to keep information manageable. By combining metadata, classification, and search technologies, naming conventions provide a foundation for people and software to find the information they need quickly, accurately, and efficiently.
FAQs
1. Are naming conventions still important if a system has search capabilities?
Yes. Search tools are powerful, but meaningful file names provide immediate contextual information, improve search results, and make information easier for users to identify, even before the document is opened.
2. Should every organization use the same naming conventions?
No. Effective naming conventions should reflect the types of information an organization manages, its work processes, and how employees typically retrieve documents. Naming structures should be aligned with operational needs, not a generic template.
3. Will naming conventions change over time?
Yes. As an organization grows, naming standards can be refined to support new projects, technologies, or regulatory requirements. Changes must be implemented carefully to avoid inconsistencies in existing archives.
4. Does cloud storage replace good file names?
No. Cloud platforms improve access and synchronization, but users still benefit from clear, consistent filenames when browsing folders, sharing documents, or working across multiple applications.